OpenAI's Jalapeño AI accelerator focuses on efficiency over raw power
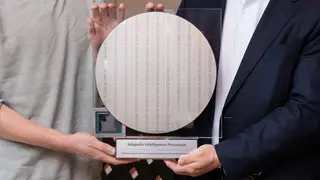
At Hot Chips 2026, OpenAI detailed its first AI accelerator, Jalapeño, which doesn't beat Nvidia's Blackwell in raw performance but offers better performance-per-watt and low latency for inference. The chip was developed using AI and targets efficiency gains. It's designed for inference rather than training.
OpenAI's move into custom silicon marks a significant shift for a company historically reliant on third-party hardware. The Jalapeño accelerator, revealed at Hot Chips 2026, was itself designed with AI assistance, reflecting a growing industry trend of using machine learning to optimize chip architectures. Its focus on inference workloads suggests OpenAI is prioritizing efficient deployment of trained models over expanding training capacity.
The decision to emphasize performance-per-watt rather than raw throughput positions Jalapeño as a complement to existing infrastructure rather than a direct competitor to Nvidia's flagship parts. By targeting low-latency inference, the chip addresses a critical bottleneck in real-time AI applications. This approach mirrors broader industry movement toward specialized accelerators optimized for specific workloads, with power efficiency becoming a key differentiator as data center energy costs climb.
The Jalapeño accelerator's efficiency focus could reshape how AI services are delivered at scale. If OpenAI deploys these chips broadly, reduced power consumption may lower operational costs and potentially influence pricing for AI products. However, its inference-only design means training workloads still depend on existing suppliers, limiting immediate disruption. Organizations running large-scale AI inference could benefit from lower energy bills, while Nvidia's dominance in training remains intact for now.