AI Red Teaming as a Security Safeguard for Brand and Data Risks
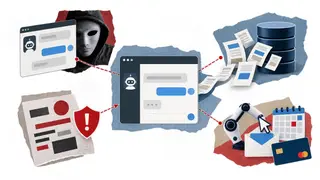
The article reports that businesses are deploying AI capabilities more quickly than security teams can review them, which opens fresh avenues for attackers. It outlines AI red teaming as an adversarial testing method for language models, retrieval pipelines, and autonomous agents, covering risks such as manipulated prompts, leaked training data, bypassed safeguards, and unauthorized tool use. The story adds that these weaknesses can harm brand reputation, expose sensitive information, and undermine digital security.
Businesses are adding AI features to customer-facing products before security teams can evaluate them. Chatbots, generative agents, and retrieval-based systems create attack surfaces that conventional application testing does not address. AI red teaming examines large language models, retrieval pipelines, autonomous agents, and multi-modal systems for adversarial failure modes.
Such testing covers prompt injection, data poisoning, model extraction, jailbreak attempts, and misuse of connected tools. Group-IB reports real-world AI abuse in fraud, brand impersonation, and large-scale phishing. The resulting weaknesses can affect brand trust, expose sensitive data, and create digital security risks.
As AI red teaming becomes more common, customers, employees, and organizations may benefit from fewer manipulated chatbots, leaked records, and unauthorized agent actions. Brand owners could face less reputational harm from deepfake impersonation or cloned support interfaces. However, if testing lags deployment, attackers may exploit weak safeguards, affecting trust in digital services. Regulators and security teams may face pressure to keep pace.