AI Startup Tavus Launches Video Conversation Model with Near-Human Interaction Capabilities
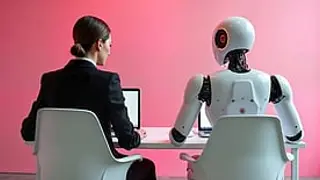
Tavus introduced Griffin, an AI model designed to conduct real-time video conversations with natural speech, facial expressions, and body movements. The system processes visual and audio signals simultaneously and responds dynamically to interruptions and tone changes during interactions. In testing, 48% of users believed they were speaking to an actual person rather than an AI system.
Tavus's Griffin represents a technical advancement in multimodal AI systems that process multiple communication channels simultaneously. Rather than generating responses after user input ends, the system operates continuously, monitoring facial expressions, speech patterns, and interruptions to adjust outputs in real-time. The company's testing methodology showed that nearly half of participants in live demonstrations could not reliably identify Griffin as artificial, suggesting the system achieves a meaningful threshold in behavioral mimicry.
The model integrates several specialized AI functions—video generation, speech processing, and conversational logic—into a unified framework designed for two-way interaction rather than question-answering sequences. Currently restricted to limited early testing through Griffin-Lite, the technology remains under development as Tavus prepares disclosure and safety protocols for eventual wider deployment.
Griffin's capabilities could reshape sectors relying on live interaction, potentially streamlining customer service, education, and training applications. However, the technology raises concerns about authentication and informed consent, particularly if applied to hiring processes where deception about a participant's nature could compromise fair assessment. Wider adoption may necessitate regulatory frameworks clarifying disclosure requirements and acceptable use contexts, as the gap between AI and perceived human interaction narrows considerably.